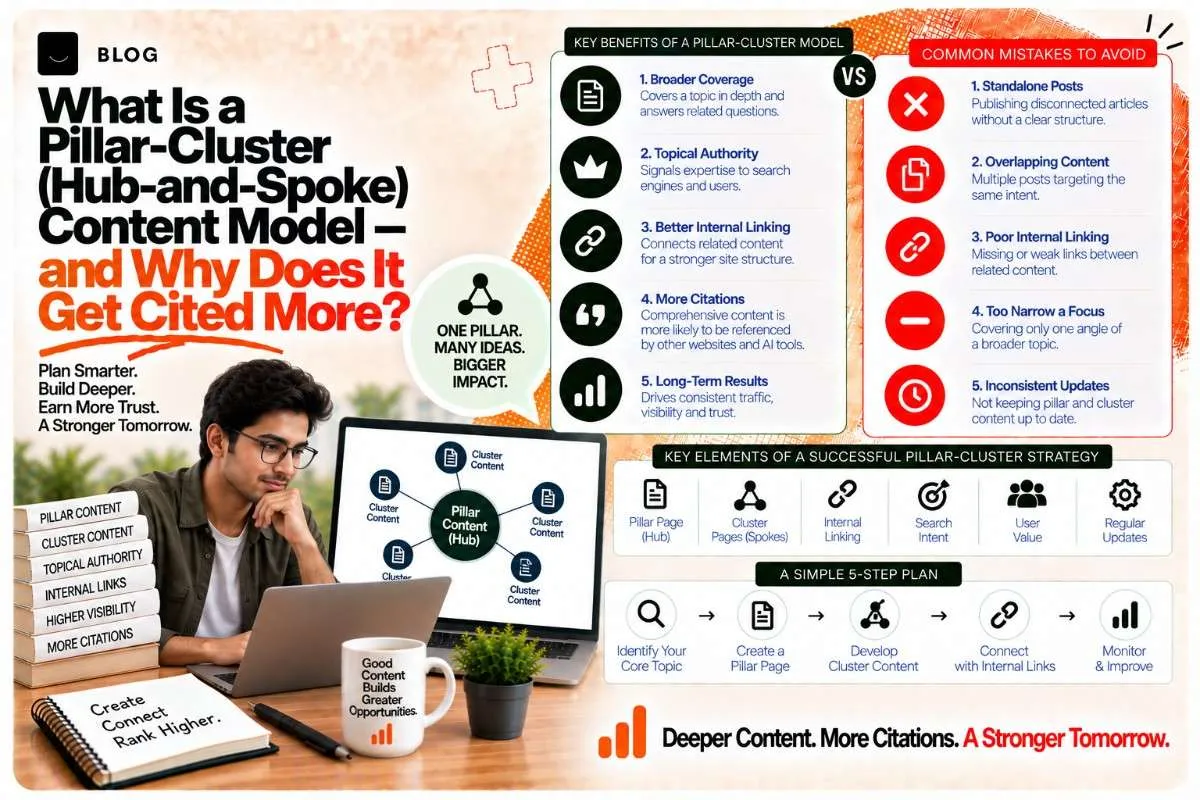
What Is a Pillar-Cluster (Hub-and-Spoke) Content Model — and Why Does It Get Cited More?
A pillar-cluster model, also called hub-and-spoke, is a way of organising content so one comprehensive page on a broad topic links out to several narrower pages that each go deep on one specific angle of it — and those narrower pages link back to the pillar and to each other. The structure sounds like an information-architecture detail. In practice it is one of the more reliable ways to build the kind of topical depth that both search engines rank well and AI answer engines cite confidently, because it solves a problem scattered, unconnected posts cannot: it gives a system a clear signal of where genuine expertise on a topic actually lives.
The two names for the same idea
"Pillar-cluster" and "hub-and-spoke" describe the same structure from two different angles, and the terms get used more or less interchangeably across the industry.
Pillar-cluster emphasises the content itself: one pillar page covering a topic broadly, and several cluster pages each covering one specific sub-topic in depth.
Hub-and-spoke emphasises the linking structure: a hub page at the centre, with spoke pages radiating out from it, each connected back to the hub.
Both describe the same three things happening at once: a broad page, several narrow pages, and a deliberate linking pattern connecting them. This post uses both terms, since a reader searching for either should land on the same explanation.
What a pillar page actually is
A pillar page covers a broad topic comprehensively enough to serve as a genuine starting point — not exhaustively answering every sub-question in full depth itself, but mapping the topic's real shape and linking out to the cluster pages that go deep on each part.
This library's own Generative Engine Optimization pillar is a working example: it defines what GEO is, explains the core mechanism, and links out to narrower posts covering measurement, local application, vernacular content, and vertical-specific execution — rather than trying to cram all of that depth into one page.
A pillar page that tries to be both broad and maximally deep on every sub-topic usually ends up too long to be genuinely useful and too shallow on any single angle to compete with a dedicated page. The pillar's job is orientation and connection, not exhaustive coverage.
What a cluster page actually is
A cluster page goes deep on one specific angle of the pillar's broader topic — narrow enough to be genuinely thorough, and clearly positioned as part of a larger topic through its links back to the pillar and sideways to related cluster pages.
Within this library, the four posts on measuring GEO — an audit method, an ROI framework, a reframing of what KPI to track, and how to keep results once earned — are a cluster. Each is narrow and complete on its own specific angle. Together, linked to each other and to the pillar, they demonstrate depth on GEO measurement specifically that no single page could hold without becoming unreadable.
Why this structure works better than scattered posts
For a search engine
A cluster concentrates topical relevance signals across several interlinked pages rather than spreading them across unconnected posts that each compete faintly for overlapping terms. A search engine crawling a well-built cluster encounters clear evidence that a site has genuine, structured depth on a subject — not just one post that happens to mention it.
Internal linking within a cluster also distributes authority more efficiently than isolated pages can. A cluster's pillar typically earns more external links and more direct traffic than any individual cluster page; routing that authority down to the narrower pages through consistent internal linking, and routing engaged readers from narrow pages back up to the pillar, keeps the whole structure working as a coherent unit rather than a set of disconnected assets.
For an AI answer engine
This is where the structure matters even more directly than it does for conventional ranking, and it connects to the entity clarity argument covered in this library's Entity SEO Playbook.
An AI system assembling an answer is, in effect, assessing which source demonstrates genuine authority on a topic. A single isolated post making a claim is one data point. A pillar linked to eight cluster pages, each internally consistent with the others and each demonstrating real depth on a distinct facet of the same subject, is a considerably stronger signal that the site genuinely knows the territory — closer to how a careful human researcher would judge whether a source is a genuine expert or someone who wrote one plausible-sounding post.
This also connects directly to the query fan-out behaviour covered in our post on optimising for Google's AI Mode: a system decomposing a broad question into several related searches is more likely to find good answers across a well-built cluster, because the cluster was built to cover exactly that kind of topical breadth by design.
The mechanism: why internal linking is doing more work than it looks
The links themselves are not decoration. They are the structure's actual mechanism, in three specific ways.
They tell a crawling system what belongs together. A search engine or AI crawler encountering a pillar linking out to eight related pages, each linking back, learns the shape of the topic directly from the link graph — which is a far stronger signal than inferring topical relationships from keyword overlap alone.
They distribute authority to where it is needed. A pillar page typically accumulates the most external links and direct visits. Internal links carry some of that accumulated authority down to the narrower cluster pages that would otherwise struggle to rank or get cited on their own.
They keep a reader — human or AI — moving through the whole topic rather than bouncing after one page. A reader who arrives at one cluster page and finds a clear path to the pillar and to adjacent cluster pages engages with more of the site's actual depth, which is itself a positive signal most systems weigh in some form.
How to build one from an existing scattered blog
Most businesses starting this work already have blog posts — just not organised this way. The practical process:
- Group existing posts by underlying topic, regardless of when they were published or how they were originally categorised. Several posts probably already cluster around a shared subject without ever having been linked to each other.
- Identify which post, if any, could serve as the pillar — usually the broadest, most foundational piece on the topic. If none exists, that is the gap to fill first.
- Add the missing links. This is often the fastest, highest-return step: going back through existing posts and adding the pillar-to-cluster and cluster-to-cluster links that should have existed from the start. This library's own linking workbook documented exactly this kind of retrofit work across dozens of existing posts.
- Identify genuine gaps — sub-topics the cluster should cover but does not yet — and prioritise filling those over starting an entirely new cluster.
How to build one from nothing
- Pick a topic broad enough to sustain several distinct cluster pages, narrow enough to stay coherent. "Digital marketing" is too broad to cluster meaningfully. "Generative Engine Optimization" is workable, as this library demonstrates.
- Map the topic's genuine sub-questions before writing anything — the same fan-out thinking covered in our AI Mode post, applied to planning rather than to an existing page.
- Write the pillar first, covering the topic's shape and explicitly noting where deeper content will live, even before every cluster page exists.
- Build cluster pages progressively, linking each new one back to the pillar and to relevant existing cluster pages as it publishes, rather than waiting to link everything retroactively once the whole cluster is finished.
What makes a cluster genuinely distinct rather than duplicate
This is the most common way a cluster fails, and it deserves its own section because getting it wrong actively hurts rather than merely underperforming.
Each cluster page needs a genuinely distinct angle — a different sub-question, a different vertical application, a different stage of the same process — not a rewording of the same content with a different headline. Two cluster pages that substantially overlap compete with each other for the same queries and dilute the cluster's signal rather than strengthening it, the same cannibalisation risk this library flags explicitly whenever two posts sit close to the same territory.
A useful test before publishing a new cluster page: could a reader who has read the pillar and the existing cluster pages learn something genuinely new from this one, or would they recognise it as saying the same thing again in different words? If the honest answer is the second, the topic needs a narrower or more specific angle, or it does not need its own page at all.
A worked example
This library's own local SEO content demonstrates the pattern, even though it was not planned as a single formal cluster from day one.
The pillar-equivalent role is served by the broad local SEO comparison content. Around it sit genuinely distinct cluster pages: one on how a specific platform change altered local discovery, one on practical local wins a restaurant can ship quickly, one on multi-location structure for franchises and clinic chains, one on the review-velocity mechanism specific to the map pack, and one giving local SEO its dedicated doctor-specific application. Each covers a distinct angle — a platform event, an operational checklist, a structural scaling problem, a ranking-factor mechanism, a vertical application — and each links to the others where genuinely relevant, without repeating the same explanation of what local SEO is in each one.
Common mistakes that quietly break the model
Building the cluster pages before the pillar exists, leaving narrow content with nothing broader to link up to, and no page positioned to receive the cumulative authority the cluster should be building toward.
Letting cluster pages drift toward duplicate territory over time, especially as new posts get added by different people without checking what already exists — the exact reuse and overlap risk this library's own working process now checks for explicitly before publishing anything new.
Linking only from the pillar down, never sideways between cluster pages. A true hub-and-spoke structure benefits from spokes referencing each other where genuinely relevant, not only radiating from a single centre.
Treating the cluster as finished once built, rather than as a structure that needs new spokes added as genuine gaps are identified and existing spokes refreshed as the topic evolves — the same ongoing discipline covered in this library's dedicated post on content freshness.
How to tell whether it is working
Three signals worth tracking, though none in isolation is conclusive:
Whether cluster pages rank and get cited more strongly than comparable standalone posts on the same site did previously — a genuinely difficult before-and-after comparison to run cleanly, but worth a rough read over several months.
Whether the pillar page itself gains authority and traffic over time as cluster pages accumulate beneath it, which is the structure's core hypothesis in action.
The same manual AI citation testing method used throughout this library — running real buyer-intent prompts related to the cluster's topic across AI platforms, and checking whether cluster pages specifically, rather than isolated unrelated content, are the ones getting cited.
Frequently asked questions
A way of organising content where one comprehensive pillar page covers a broad topic and links out to several narrower cluster pages, each going deep on a specific angle of that topic, with the cluster pages linking back to the pillar and to each other. It concentrates topical authority in a connected structure rather than spreading it across unrelated posts.
Yes, they describe the same underlying structure from two angles. Pillar-cluster emphasises the content itself — a broad page and several narrow ones. Hub-and-spoke emphasises the linking pattern — a central hub with spoke pages radiating outward and connecting back. Both terms are used interchangeably across the industry.
An AI system assessing whether to cite a source is, in effect, judging whether that source demonstrates genuine authority on a topic. A single isolated post is one data point. A pillar linked to several genuinely distinct, internally consistent cluster pages is a considerably stronger signal of real depth than one page making a similar claim alone.
There is no fixed number — what matters is that each cluster page covers a genuinely distinct sub-topic rather than restating the same content differently. A pillar with three genuinely distinct, substantial cluster pages is more effective than one with ten pages that overlap and dilute each other's relevance.
Generally the pillar first, even if not every cluster page exists yet, since it establishes the topic's shape and gives early cluster pages something to link up to. Cluster pages can then be built progressively, each linked in as it publishes rather than retrofitted all at once at the end.
Letting cluster pages drift into overlapping, near-duplicate territory over time, especially as new content gets added without checking what already exists in the cluster. Overlapping cluster pages compete with each other for the same queries and weaken the cluster's overall signal rather than strengthening it.
Yes, and this is often faster than starting from nothing, since many existing posts likely already cluster around shared topics without having been linked to each other. Grouping existing posts by topic, identifying or writing a pillar, and adding the missing internal links is usually the highest-return first step.
Ready to build what's next?
Tell us where you're headed. We'll come back with a plan to get there.
Book an intro call