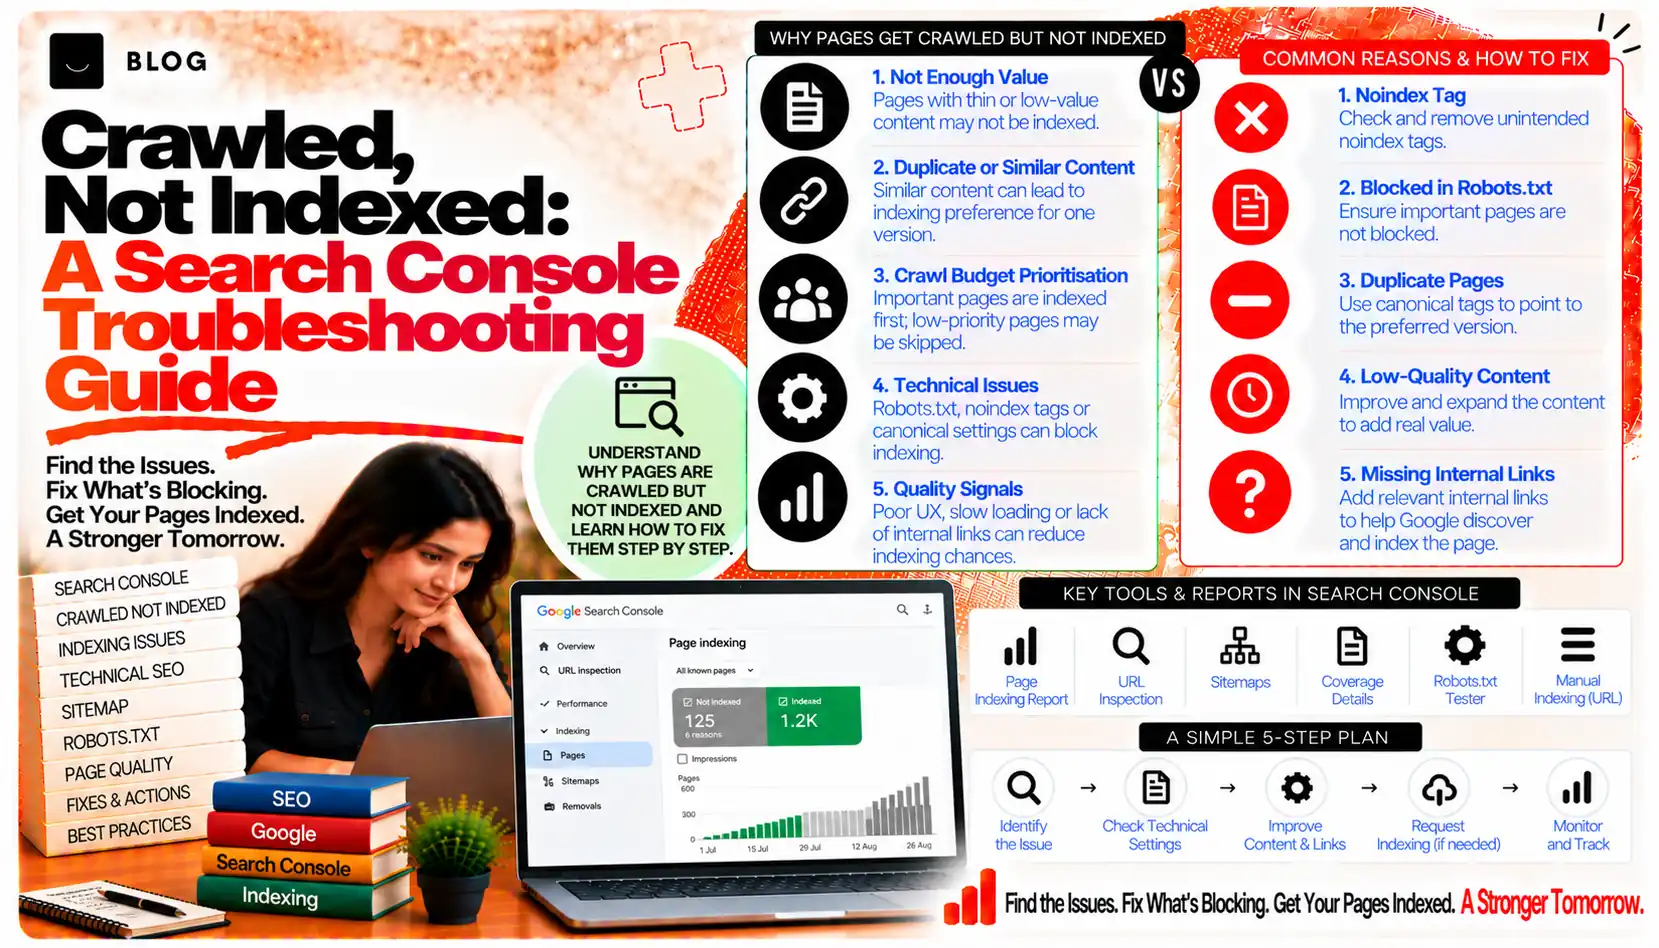
Crawled, Not Indexed: A Search Console Troubleshooting Guide
Few things frustrate a site owner more than a page that Search Console says is known to Google but not in search. The indexing report lists it under a status such as "Discovered – currently not indexed" or "Crawled – currently not indexed", and the explanation is short and vague. The page exists, the content looks fine, and it still does not appear for the queries it was written for.
These statuses describe what Google has done with a URL, not why. They are a starting point for diagnosis. The useful question is which stage the page has reached, and what is stopping it from going further. Each status points to a different family of causes, and the fixes differ. Treating every unindexed page the same way wastes effort, and often makes the problem worse.
This guide walks through the main statuses, the checks that separate likely causes, and the fixes in order of how often they apply.
What the indexing statuses mean
Search Console groups pages by where they stopped in the process. The two most common unindexed statuses are:
Discovered – currently not indexed. Google knows the URL exists, usually from a link or sitemap, but has not fetched it yet. The URL is in a queue.
Crawled – currently not indexed. Google has fetched the page, and has chosen not to add it to the index at this time.
Search Console also reports pages excluded for other reasons, such as a noindex directive, a canonical pointing elsewhere, or a redirect. Those are usually deliberate or easy to check, and they are covered in Step 2.
Google's own descriptions of these statuses are brief and do not list every cause. Treat them as a guide, and check the current Search Console documentation for any changes.
Step 1: Confirm the URL is the one you intend to index
Before diagnosing anything, make sure the URL in the report is the right one. Duplicate versions cause a surprising share of unindexed status.
Check for:
- Trailing slash and non-trailing slash versions
- HTTP and HTTPS, and www and non-www variants
- Parameter versions with tracking codes or filters
- Uppercase or lowercase variants of the same path
Use the URL Inspection tool on the exact URL. It shows the canonical Google has selected, which may be a different page. If Google's chosen canonical is not the page you want indexed, that is the first problem to fix.
Step 2: Rule out direct blocks
Some exclusions are direct and easy to confirm.
- Noindex directive. Check the meta robots tag and any X-Robots-Tag HTTP header. A noindex tag left over from staging is a common cause after launch.
- Canonical pointing elsewhere. If the canonical tag names another URL, Google is being told to index that page instead.
- Robots.txt blocking. A disallow rule stops crawling, which can produce a discovered-but-not-crawled status. Check the rules that apply to the path.
- Redirects. A page that redirects will not be indexed at its original address.
- Soft 404. A page that returns a 200 status but contains little or no real content can be treated as an error.
If any of these applies, fix it first. Re-run URL Inspection and request indexing once the directive is resolved.
Step 3: Diagnose the discovered, not crawled pattern
When a page is discovered but not crawled, Google has found the URL but has not fetched it. The usual causes concern how Google allocates its crawling, rather than the page itself.
Check the following:
- Internal links. Pages with few or no internal links from crawled, important pages are less likely to be fetched promptly. Add links from relevant, well-linked pages.
- Sitemap quality. A sitemap full of low-value, duplicate or error URLs can dilute attention. Keep it to canonical, indexable pages. The IndexNow and sitemaps post covers sitemap hygiene in detail.
- Server response. Slow or unreliable responses reduce how much Google is willing to fetch. Check response times and error rates in the crawl stats report.
- Scale. Very large sites with many URL variants may see slower crawling of new pages. Reducing unnecessary URLs helps more than requesting indexing for each one.
Requesting indexing for a single URL can help for a handful of important pages. It does not solve a structural problem across many pages.
Step 4: Diagnose the crawled, not indexed pattern
When a page is crawled but not indexed, Google has seen the content and decided not to keep it. This status is more often about quality, uniqueness and signals than about access.
The most common causes are:
- Thin content. The page offers little beyond what is available elsewhere, or contains only a few sentences.
- Duplicate or near-duplicate content. The same text appears on other pages of the site or on other sites, so Google chooses one version.
- Low distinct value. Pages in a large set of similar pages, such as location or product variants with minor differences, may be judged redundant.
- Weak internal signals. Pages with few links may not be treated as important enough to keep.
- Quality concerns across the site. When many pages are low quality, individual pages can struggle to be indexed.
The fixes here are content and structural, not technical. Improve the page so it offers something distinct and useful. Consolidate near-duplicates. Link the page from stronger pages. The content pruning post covers when to remove or merge weak pages, which is often the right response across a set of similar URLs.
Step 5: Use the status pattern across the site
A single unindexed page is a question. A pattern across many pages is a diagnosis. Export the list of unindexed URLs from the indexing report, and group them by template, directory and parameter pattern.
Look for:
- A whole directory or template that is crawled but not indexed
- Parameter URLs that dominate the discovered list
- New pages that remain discovered for weeks while older pages are indexed
A pattern points to a cause that affects many URLs at once, such as a template with thin content, a filter that generates duplicates, or a section with no internal links. Fixing the pattern is more effective than working through individual URLs.
Step 6: Check the signals that the page sends
Several signals help Google decide whether a page deserves to be indexed. Review the page against them.
- Clear topic. The title, H1 and opening paragraph state what the page is about.
- Real substance. The page answers a specific need in more depth than a summary or a placeholder.
- Internal links. The page is linked from relevant pages with descriptive anchor text.
- Consistent canonical. The page's canonical points to itself, unless there is a deliberate reason otherwise.
- Freshness where relevant. For topics that change, the page shows current, accurate information. The content freshness post covers when an update is meaningful.
Improve the page against these signals before requesting indexing again. Requesting indexing without a change is unlikely to help if the page has not changed the signals.
Step 7: Request indexing sparingly, and then wait
Once the cause is addressed, request indexing for the important pages using URL Inspection. Do this for a limited number of URLs, not an entire backlog. Requests are a prompt, not a guarantee.
After a fix, allow time. Indexing can take days or weeks, and the status may remain for a while even after the page is eligible. Check the indexing report again after a reasonable interval, rather than repeating requests.
Step 8: Know when the problem is outside the page
Sometimes a page remains unindexed because the site as a whole has a quality or trust problem, or because the page targets a query that is already well served. In those cases, improving the individual page has limited effect.
Consider whether:
- The page's topic is already covered by a stronger page on the site, in which case consolidation is better than indexing both
- The site has a broad pattern of thin or duplicate content, which needs a site-level response
- The page targets a query where competitors are far stronger, and the page's value is not yet clear enough to justify a place in the index
Be honest about these cases. The fix may be to consolidate, to improve the site overall, or to accept that some pages do not need to be indexed.
What troubleshooting cannot do
It cannot force Google to index a page. Search Console reports what Google has decided, and the tools give a prompt for re-evaluation, not a guarantee. It cannot repair a site that publishes large volumes of thin content, and it cannot compensate for a page that offers little that is not already available. The most effective response to a persistent unindexed status is usually a stronger page, not more requests.
Common troubleshooting mistakes to avoid
Requesting indexing repeatedly without a change. It adds noise and does not alter the signals.
Treating every status the same way. Discovered and crawled statuses have different causes.
Ignoring the canonical Google has chosen. If it points elsewhere, the page will not be indexed on its own.
Fixing URLs one at a time. A pattern across many pages needs a pattern-level fix.
Leaving a staging noindex in place. It is a simple cause that is easy to miss after launch.
Adding more thin pages to fix indexing. This worsens the quality signals the report is describing.
Frequently asked questions
Google knows the URL but has not crawled it yet. It usually reflects how Google queues crawling, along with internal links, sitemap quality and server responses.
Google has fetched the page and chosen not to index it at this time. This usually points to content quality, duplication or weak internal signals.
It can prompt a re-evaluation, but it does not guarantee indexing. It works best after the underlying cause has been addressed.
New pages often need several weeks before the status changes. Act sooner if the page is important and the status has persisted after the basic checks have passed.
Yes. A noindex directive removes the page from indexing, and the report may show it as excluded rather than crawled. Check the page's directives first.
Not automatically. Decide whether the page has a distinct purpose. If it does, improve it. If it duplicates another page, consolidate. If it has no value, remove it with a sensible redirect or status code.
Ready to build what's next?
Tell us where you're headed. We'll come back with a plan to get there.
Book an intro call